Synthetic Datasets for Computer Vision Training

Real world Synthetic Dataset, that trains your algorithm to see beyond what you see!
Synthetic Dataset data that mimics production data might not be complete for obvious reasons.
Train your Computer Vision Algorithms such as Document Classifier Algorithms, with data that considers real world variables and are statistically significant, so that they can see beyond what you see in the real world.
HaiData’s proprietary synthetic document dataset generation methodology based on large scale generative modelling and Domain randomization provides data that is well balanced with consistent sampling, accommodating rare events, so that it can enable superior simulation and training of your models.
HaiData currently provides synthetic document datasets in the following domains and use cases.
- Internal Services - Visa application, Passport validation, License validation, Birth certificates, Driver's license
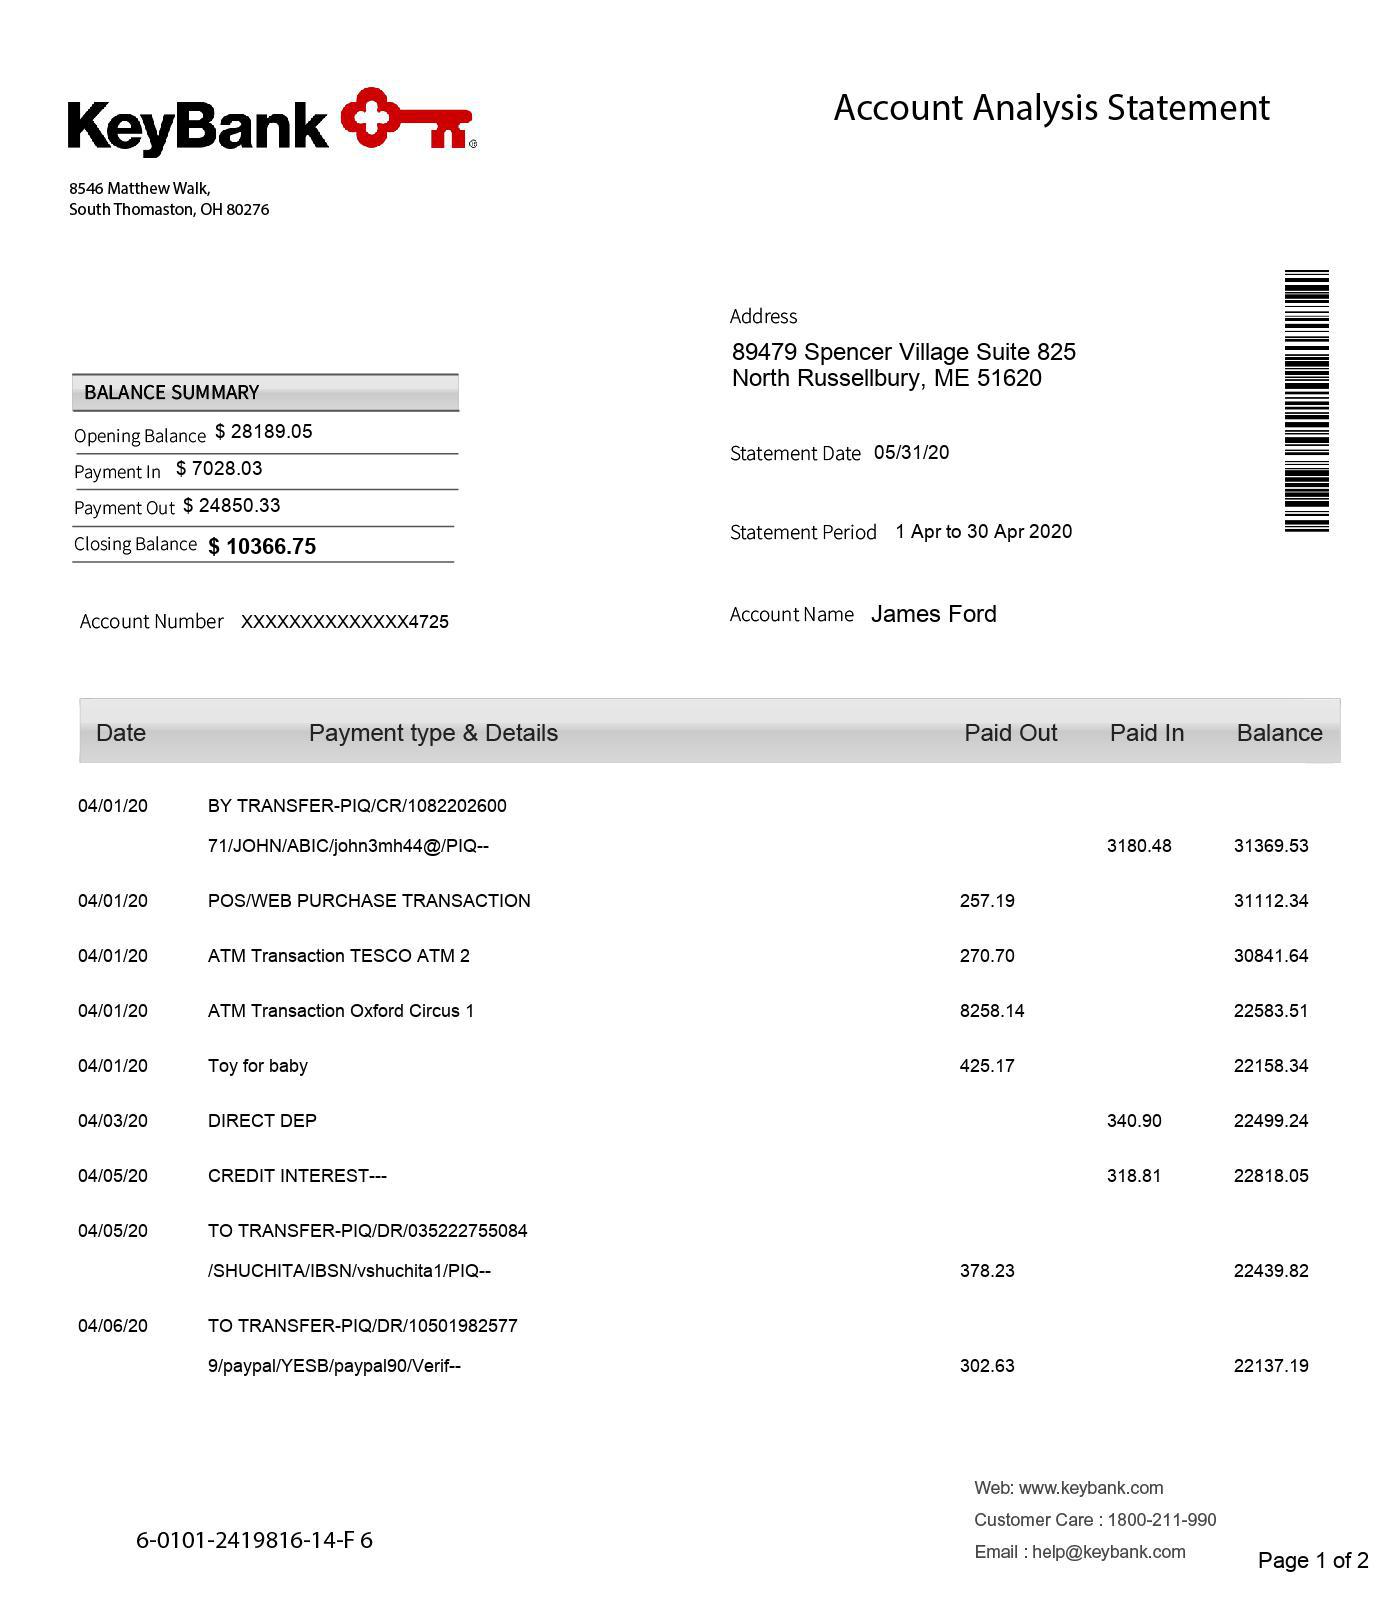
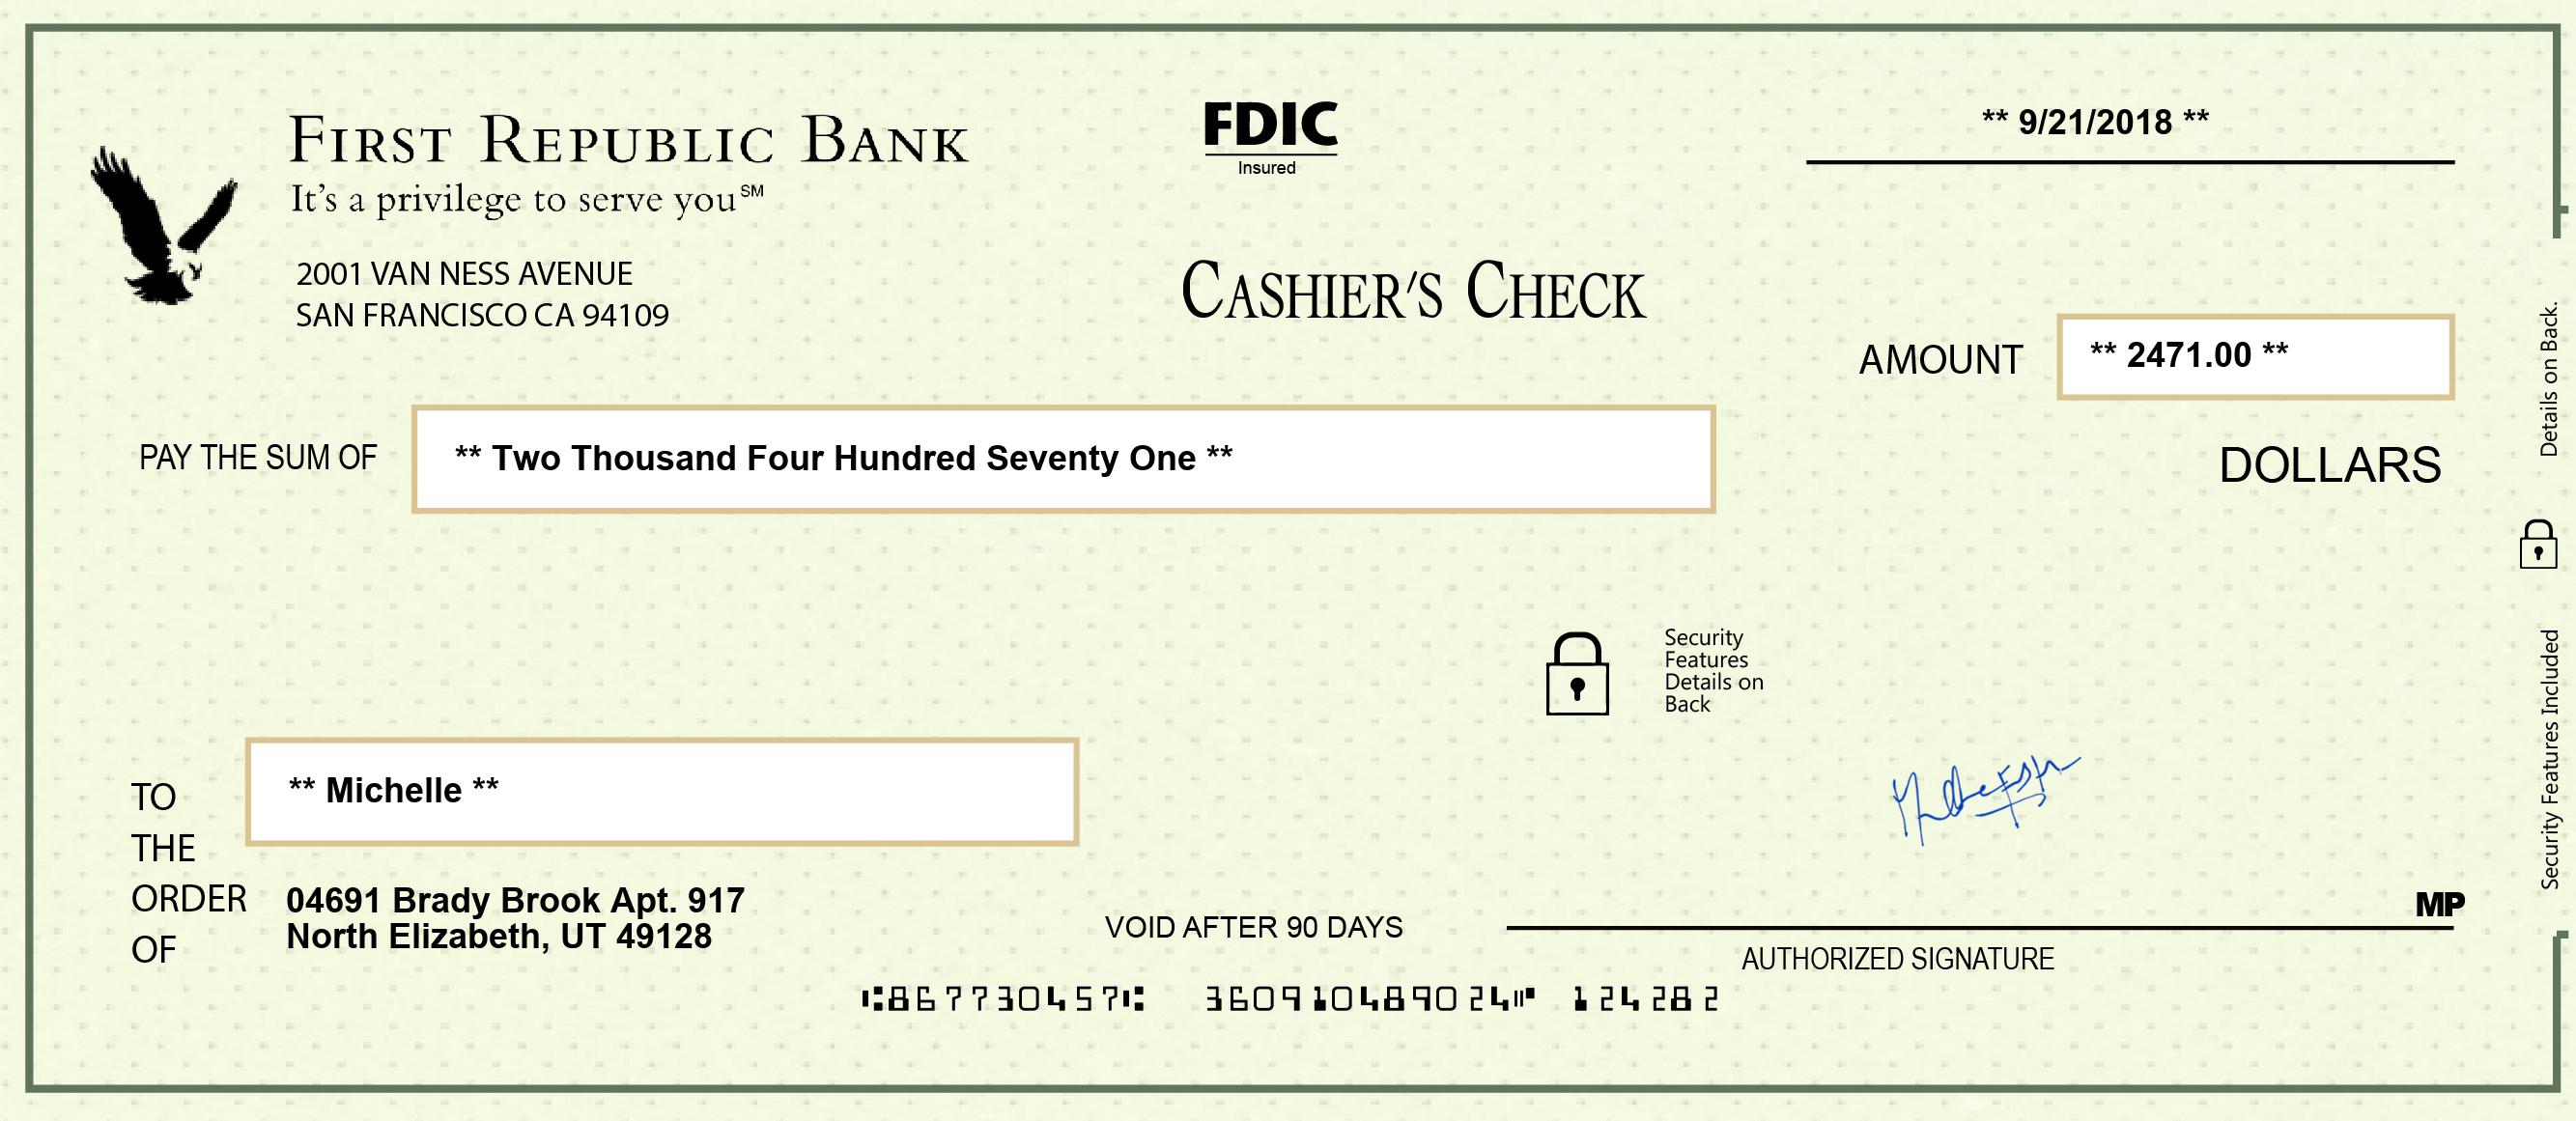
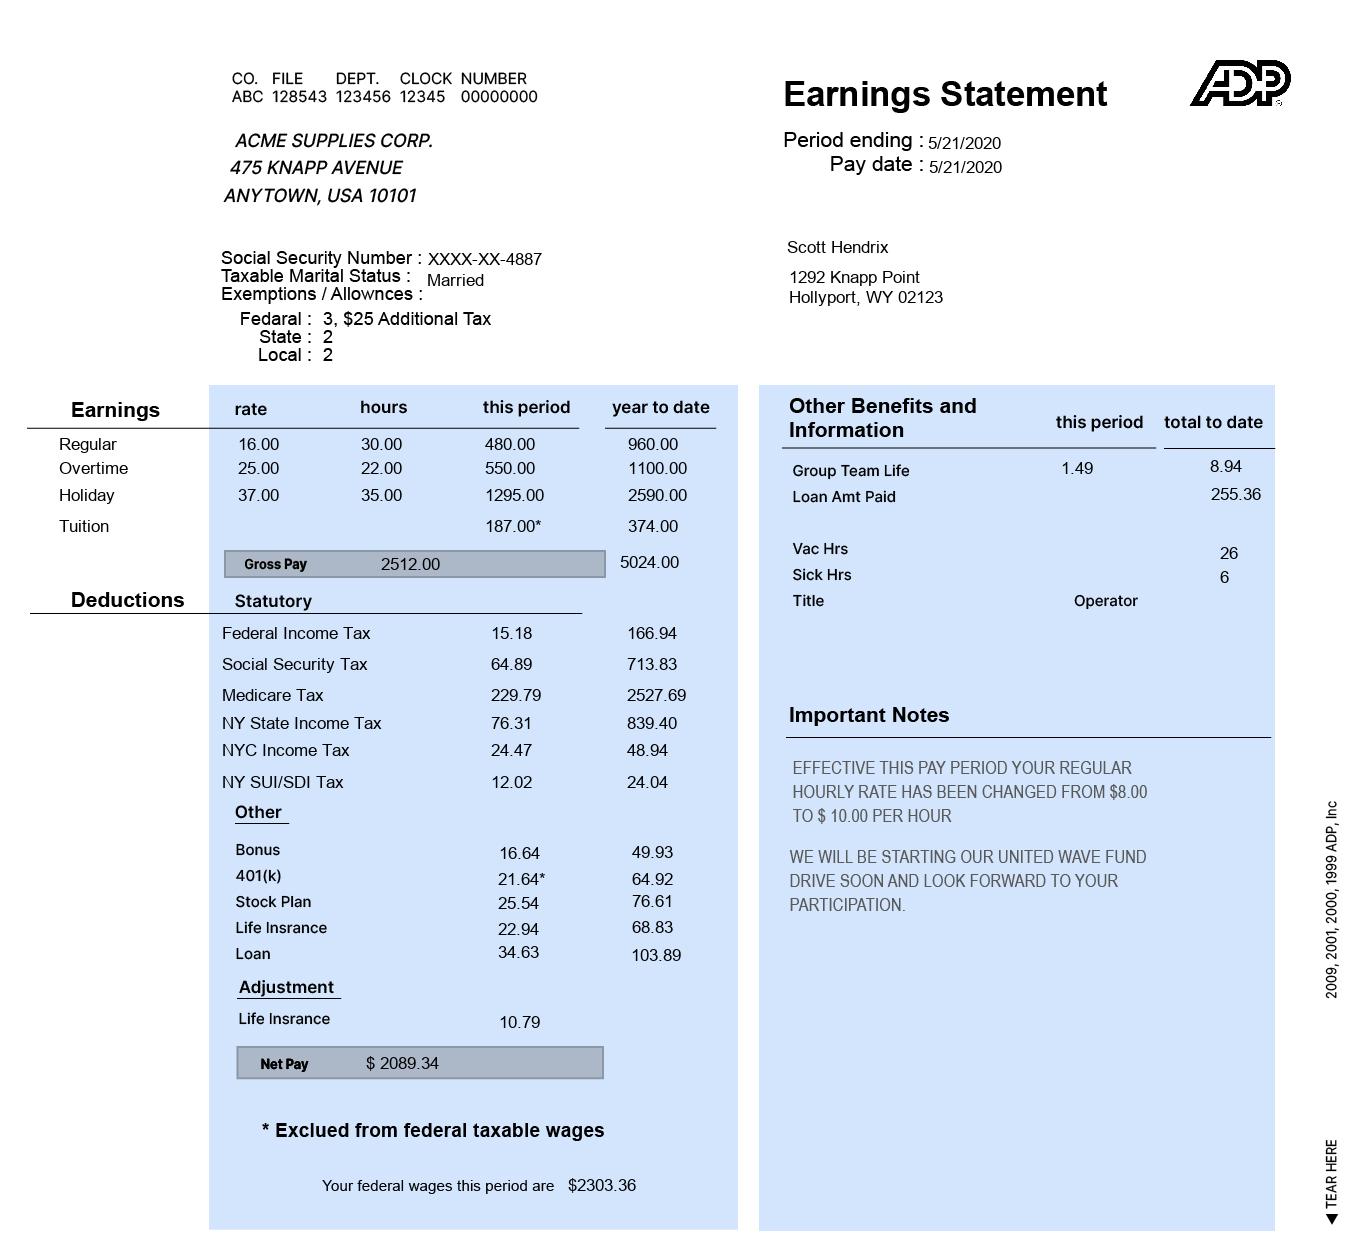
- Financial Services - Bank checks, Bank statements, Pay slips, Invoices, Tax forms, SSN ID Cards, Insurance claims and Mortgage/Loan forms and more
- Healthcare - Medical Id cards
We also design and develop new synthetic documents as per customer requirements.
Where Synthetic Datasets Are Used
Synthetic data helps train computer vision models where real data is scarce, imbalanced or sensitive. Common application areas include:
- Document classification and OCR - training on synthetic bank statements, checks, payslips, invoices and ID cards.
- Rare-event coverage - generating edge cases and uncommon layouts that are hard to collect in the real world.
- Data balancing - filling class gaps with consistent sampling for more robust models.
- Privacy-sensitive domains - reducing reliance on real personal data in finance, healthcare and identity workflows.
- Model simulation and testing - stress-testing algorithms against controlled, statistically significant variation.
Why HaiData for Synthetic Datasets
- Own infrastructure - built on our HaiCrowd platform (own-cloud) backed by in-house GPU infrastructure.
- Human plus automated QC - multiple levels of human review combined with automated quality control checks.
- Consent-first and privacy-aware - GDPR-aligned handling aligned with India's DPDP Act 2023; ISO 27001 certification is in progress (expected 2026).
- Flexible delivery - datasets delivered to your own cloud storage in the formats your pipeline needs.
- Trusted background - NVIDIA Inception Program member and GoodFirms-recognized, based in India and serving clients worldwide.
Combine synthetic data with human labeling through our data annotation services and image and video annotation.
Frequently Asked Questions
Ready to explore synthetic data for your models? Contact us to discuss your requirements.
Get in touch
For support and query:
Email us at info@haidata.ai
Ainnotate Data Technologies LLP
Prestige Tranquilty,
Budigere Cross,
Bangalore - 560049
Karnataka, India.
Sree Nagammal Bldg.
Manjoor,
The Nilgiris - 643219,
Tamil Nadu, India.

© 2026 | All Rights Reserved | Privacy Policy
HaiData is an AI Data solutions and services organization catering to the AI data needs of various industries. Started with the objective of contributing to "Data Centric AI", HaiData has invested in all aspects of the AI Data value chain - including services, technology and solutions. As an organization committed to providing jobs for technically qualified youth, who chose to work from rural places rather than cities, HaiData provides affordable AI Data related solutions and services to organizations across the world from the villages of Nilgiris hills, in India.